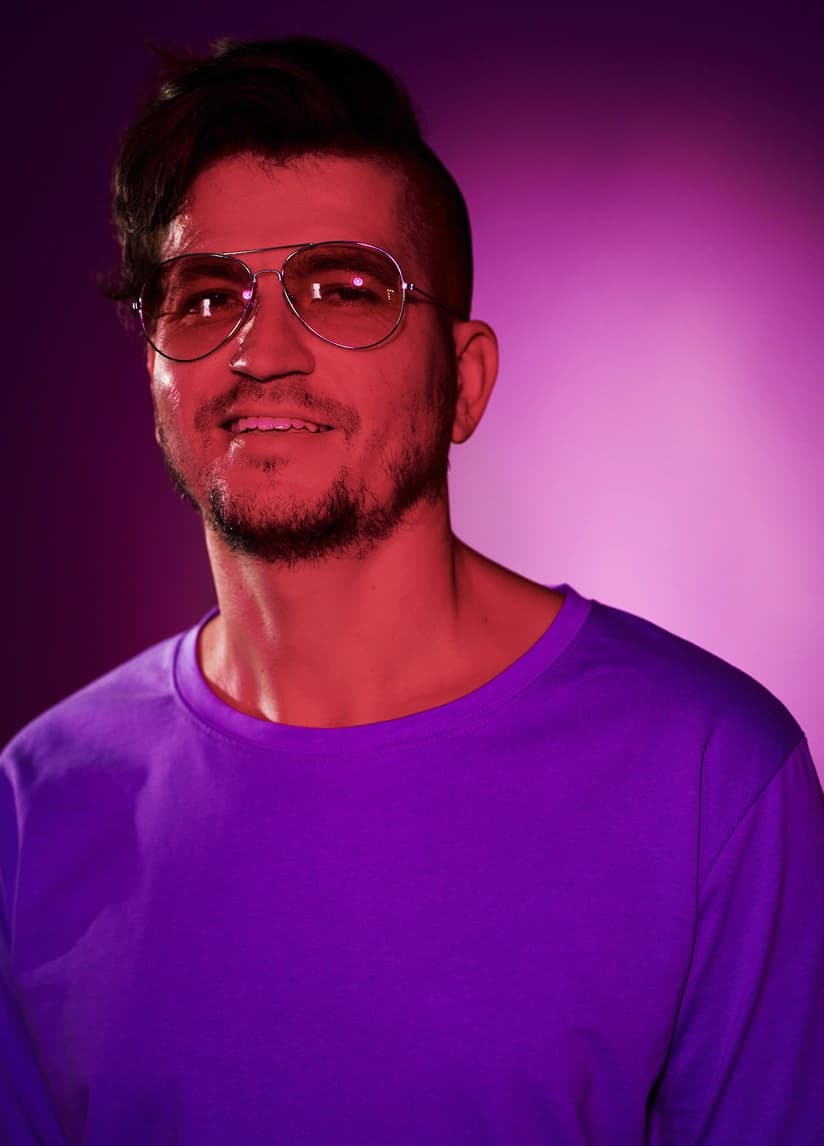
Seedream 4.0 scores 57 on our photo-anchored scale (95% interval 44–70), where a real photograph is 100. In 864 blind judgements on 48 commercial scenes it showed no measurable difference from Qwen Image 2.0: Seedream was preferred in 48.2% of judgements, ties split. GPT Image 2 was clearly ahead, preferred in 68.6%. By category, Seedream leaned ahead on social marketing and fashion, and behind on product shots, typography and street scenes.
A real photograph is pinned at 100, and every model sits by how often it won blind comparisons — the further left, the less often. Scroll sideways to see the rest of the ruler.
Prompt used:A low-angle outdoor selfie of a young woman with dark curly hair in two afro puffs, large white round earrings and a white necklace, laughing widely with her arm stretched toward the camera. She wears a mint quilted bomber jacket over a navy and white striped top with a canvas tote strap on her shoulder, and holds a glass bottle of detox water with cucumber slices and lemon. Behind her a modern building facade with pink and mint vertical louvres, ornamental grasses and a pale concrete bench.
A second mid-tier generator rather than a step up: statistically level with Qwen Image 2.0 on believability, with a different category profile. Worth routing social and fashion briefs to; keep product and typography work on Qwen Image 2.0 or GPT Image 2.
Strengths
Level with Qwen Image 2.0 on believability across the corpus
Leans ahead on social-marketing and fashion scenes
Weaknesses
Clearly behind GPT Image 2
Behind Qwen Image 2.0 on product shots, typography and street scenes
No seed control, so results cannot be reproduced exactly
Prices are for one 1024×1024 image at standard settings, checked 25 September 2026; the price at the top of the page is the average of the providers listed. Workroom pricing is on the pricing page.
Seedream 4.0 is a proprietary ByteDance model served through the BytePlus ModelArk API; its weights are not published. Terms for generated images are set by the service you generate them in.
Frequently asked questions
No measurable difference. On believability the Bradley–Terry gap is −0.07 with a 95% interval from −0.28 to +0.14, which includes zero. Across all three questions Seedream 4.0 was preferred in 48.2% of judgements with ties split, close to a coin flip. The two models differ by category rather than overall.
Clearly behind. The believability gap is −0.78 with a 95% interval from −1.03 to −0.55, which does not include zero, and GPT Image 2 was preferred in 68.6% of judgements with ties split. On the photo-anchored scale that places Seedream 4.0 at 57 and GPT Image 2 at 104.
A real photograph is fixed at 100 by definition. GPT Image 2 lands at 104.4 because its believability strength sits slightly above the photographs', but that difference is not statistically separated. A score above 100 is the scale's technical ceiling, not a claim that the images match photography.
It is the 95% interval of Seedream 4.0's score, with 56.9 as the point estimate. It is wide because 48 scenes still leave room for scene-to-scene variation, and it overlaps Qwen Image 2.0 at 64.5, which matches the head-to-head result of no measurable difference between the two.
We generated three independent images for each of the 48 commercial scenes the ladder was built on and paired them blind with Qwen Image 2 and GPT Image 2: 288 pairs and 864 judgements on prompt adherence, believability and aesthetics. The score uses believability only, against rungs frozen from the baseline study.
No. Workroom is an AI router that gives access to third-party models, including Seedream 4.0, and is not affiliated with ByteDance. The judgement-level data behind this card is published by Everypixel research under CC BY 4.0, so every number on this page can be checked against the source dataset.
About Workroom
Workroom is an AI router: we give access to third-party models, including Seedream 4.0, and we are not affiliated with ByteDance. We have no stake in any single vendor winning; the router is only useful if it sends each brief to the right model. The judgement-level data behind this card is published by Everypixel research under CC BY 4.0 and linked below, so every number here can be checked independently.
How we tested
Between 6 and 11 September 2026 we compared Seedream 4.0 blind against two fixed rungs of our quality ladder, Qwen Image 2 and GPT Image 2, on the same 48 commercial scenes the ladder was built on — three independent generations per scene, 288 pairs, 864 judgements. Every pair was judged three times, without any indication of which image came from which model, on three questions: which image follows the prompt better, which is more believable as a real photograph, and which is more attractive.
How the scale is built
Pairwise comparisons are fitted with a Bradley–Terry model; intervals come from bootstrapping over scenes. The rungs of the scale are frozen from the baseline study, so every new model lands on the same scale. The score uses believability only:
score = 100 + (strength − strength_reference) / a
model strength fitted against frozen anchor strengths from the v3 baseline; the calibration line is pinned at the photograph = 100 Category positions are fitted the same way on the 6 scenes of each category, with a real photograph pinned at 100 on every one of them.
The scale reproduced
The frozen gap between the two rungs was 0.83; this session measured 0.71 with a 95% interval of 0.45 to 1.02. The frozen value falls inside that interval.
Direct blind tests
The pairs Seedream 4.0 was judged against directly — where its place on the scale comes from.
Data: CC BY 4.0. Images: All rights reserved; provided for verification only.
Read these before reusing the data
The model ignores the requested output size: Seedream returned 2352 px on the long edge where 2048 was asked. Output was downscaled to match the ladder; it was never upscaled.
No seed control: Seedream does not accept a seed, so the three generations per scene are independent but not reproducible. This measures average ability rather than a best pick.
Prompt adherence is biased against photography, which is why the absolute score is built on believability alone.
Tie share is 28.4%, higher than the 25.4% of the original ladder study. This session pairs two models that are genuinely indistinguishable, where “equal” is an honest answer.

 Seedream 4.0